Managing Export Schedules
A schedule sends a pipeline's data to one destination on a cadence. Each run delivers one file per extract of every exporting version: the live version, plus a previous version during its 30-day overlap. A pipeline can have several schedules, for example one per destination or one daily and one weekly.
What goes into the files (data sources, extracts, filters and versions) is covered in Extracts, Drafts & Versions in Export Pipelines.
Adding a schedule
You can add a schedule in two places:
In the wizard, on the optional Schedule step of a new pipeline. It waits and starts on its next run after you publish. Click Skip for now to add schedules later.
On the pipeline page, with the New schedule button at the top, or on the Schedules tab.
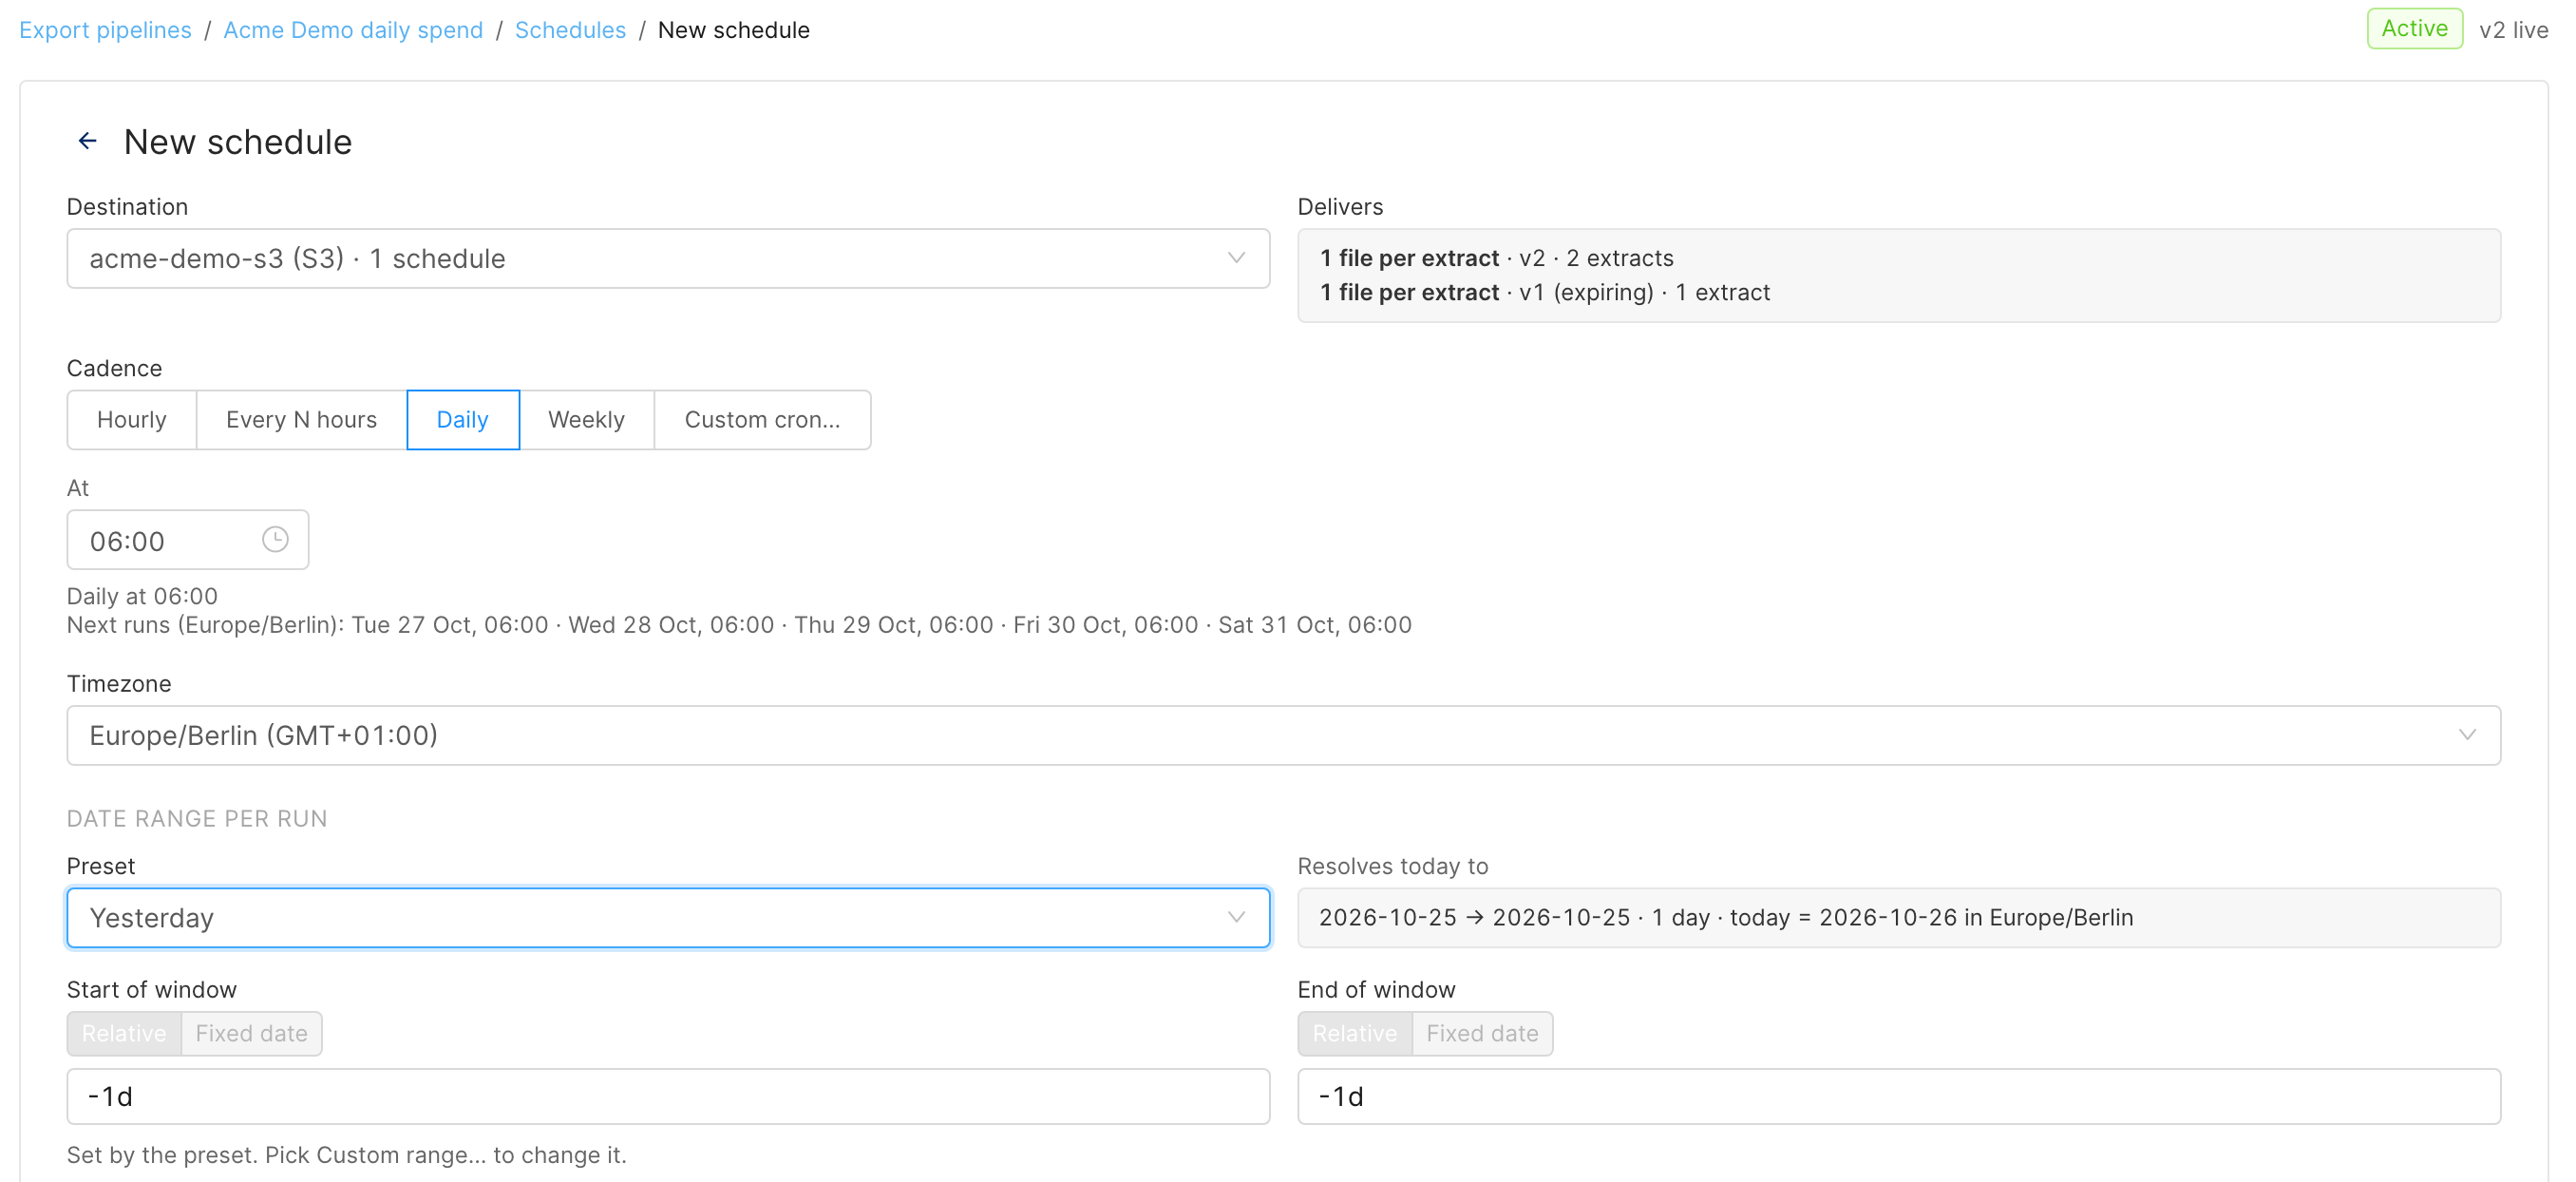
Under Destination, pick where the files go, or choose + Create new destination…. See Configuring Export Pipeline Destinations & Permissions.
Set the Cadence. We recommend Daily (see Cadence).
Check the Timezone.
Under Date range per run, pick a Preset or a custom range.
Under Output, set the compression and, if you need to, the file name template.
Click Create schedule.
Note: If the pipeline already has a live version and isn't paused, saving a new schedule usually starts an export right away. A window shows the runs as they start. If no run appears, the first export runs at the next scheduled time. After that, the schedule follows its cadence.
A pipeline can't have two schedules with the same destination and the same cadence.
Cadence
Option | Runs |
Hourly | Every hour, at the minute you pick |
Every N hours | Every 2, 3, 4, 6, 8 or 12 hours, from the first run time you pick |
Daily | Once a day at the time you pick |
Weekly | On the days you pick, at one time |
Custom cron… | Any 5-field cron expression, for example monthly |
Runs can be at most once an hour.
Under the options, Clarisights shows the next 5 runs in the schedule's timezone, so you can check the cadence before saving.
There is no monthly option: use Custom cron…. For example,
0 6 1 * *runs at 06:00 on the first day of every month.
Tip: New schedules start as Hourly with Last 7 Days. That re-exports the same 7 days 24 times a day, which is rarely what you want. For most warehouses, pick Daily at a time after your data has refreshed. See Export Scheduling & Timing Guide.
Cron examples
Times are in the schedule's timezone.
Expression | Meaning |
| Every day at 12:00 PM |
| Twice daily at midnight and noon |
| Every Monday at 8:00 AM |
| First day of every month at 6:00 AM |
Timezone
A new schedule uses Company default, which follows your company timezone. You can pick UTC or any other timezone instead. The schedule's timezone decides both when it runs and what "today" and "yesterday" mean for its date range.
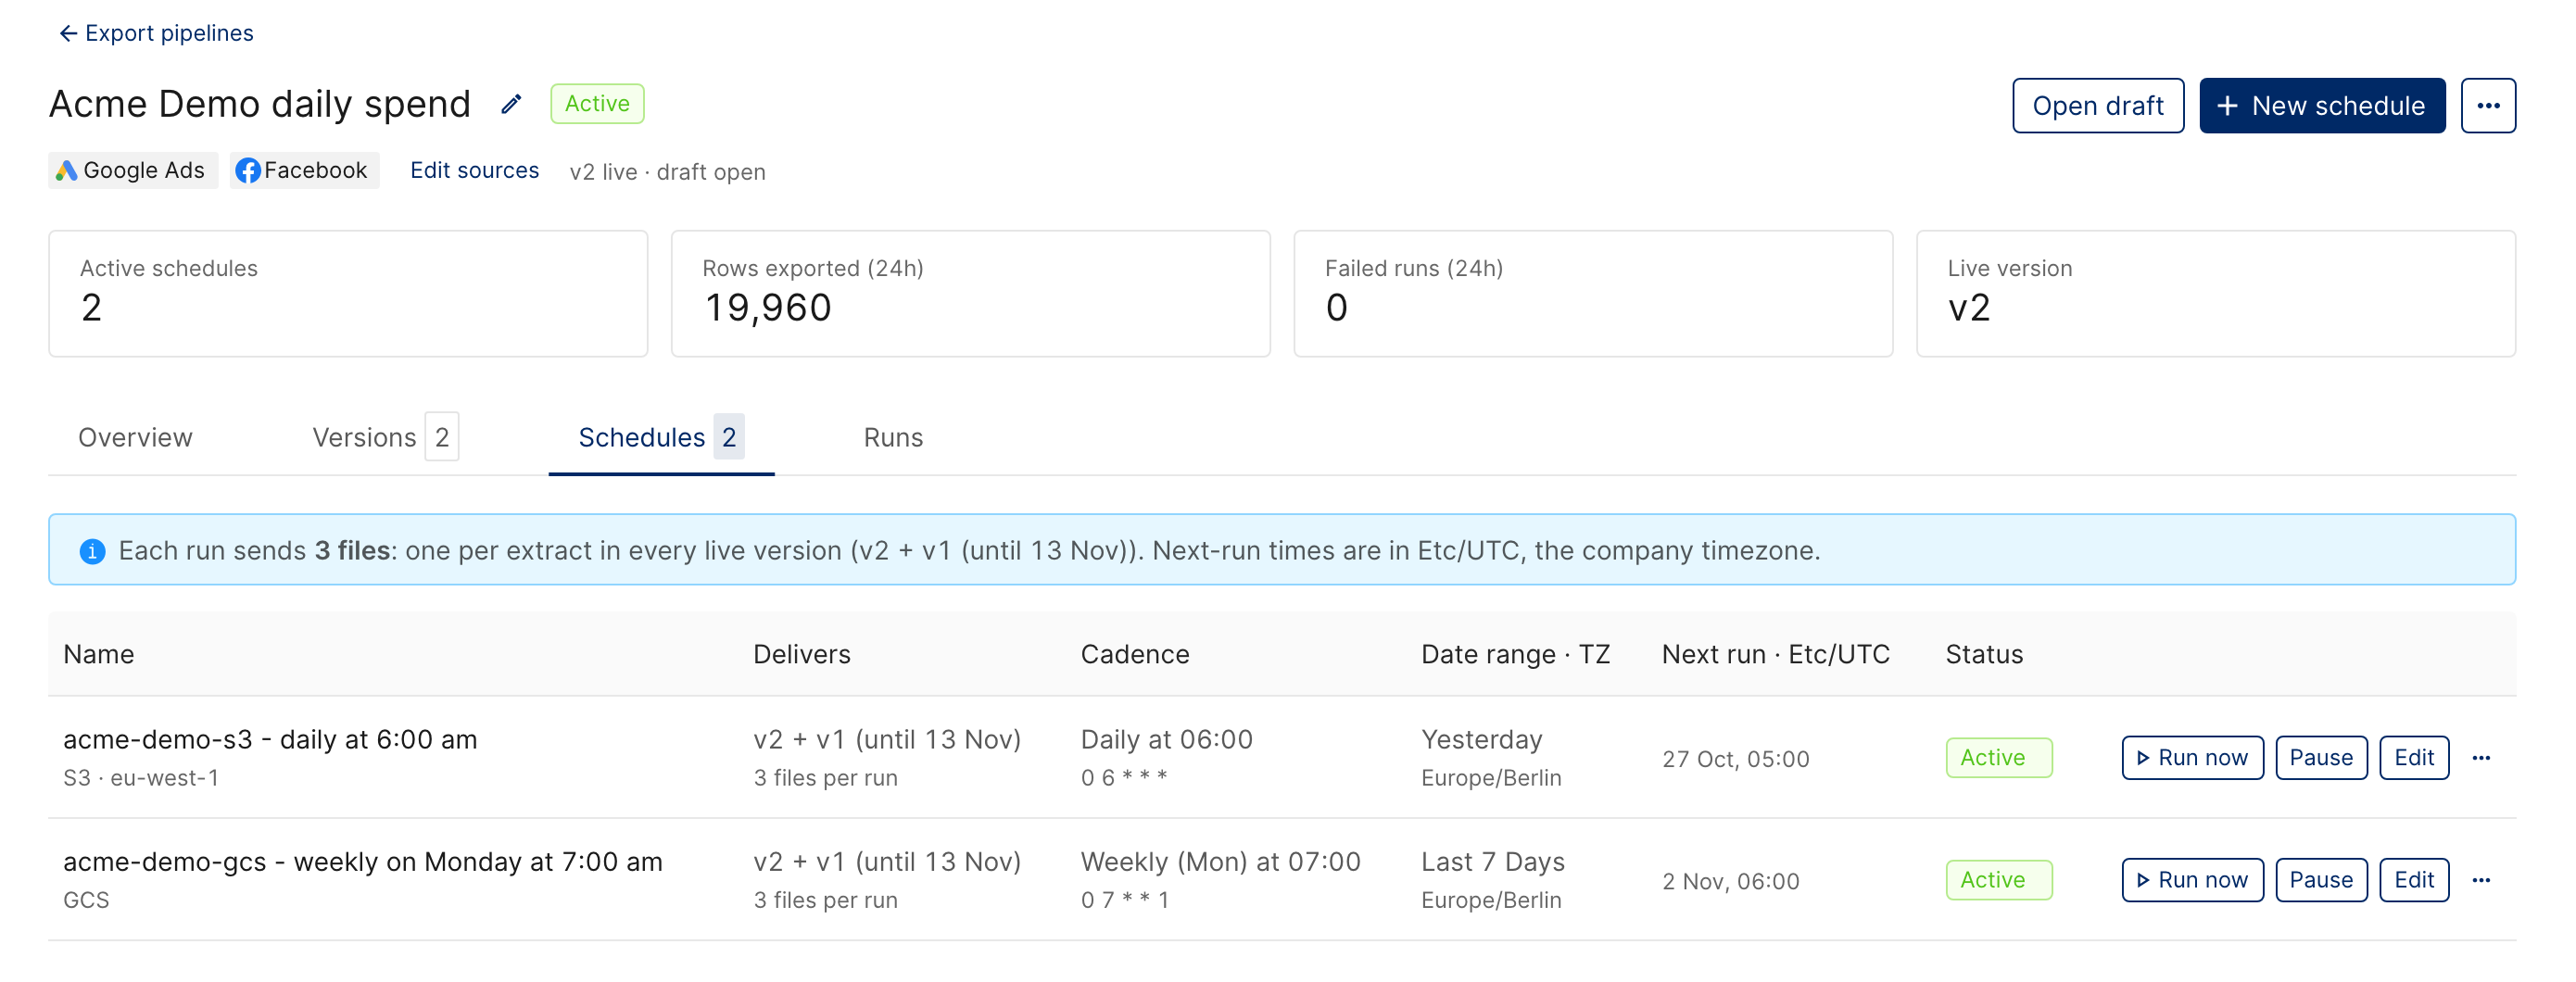
On the Schedules tab, the Next run column shows times in your company timezone.
Date range per run
Each run exports the dates set here, worked out on the day of the run in the schedule's timezone. Resolves today to shows the dates a run today would cover.
Preset | Each run exports |
Today | Today so far |
Yesterday | Yesterday |
Last 7 Days (default) | The 7 full days before today |
Last 14 Days | The 14 full days before today |
Last 30 Days | The 30 full days before today |
Last 7 Days Including Today | Today so far and the 6 days before it |
Last 30 Days Including Today | Today so far and the 29 days before it |
Custom range… | The window you set with Start of window and End of window |
For a custom range, set each end to Relative (an offset in days from the run date, such as -7d, or +0d for today) or to a Fixed date. Both ends are included. For example:
-5dto-1d: the 5 days before the run.Fixed 2026-01-01 to
-1d: from 1 January 2026 to yesterday, growing with every run.Two fixed dates: the same dates on every run.
To export a past period once, use Run now instead of a schedule.
Destination, format and compression
Destination: the storage the files go to. The list shows how many of this pipeline's schedules use each destination.
Format: CSV, with a header row.
Compression: gzip (.gz) by default, or none.
File name template
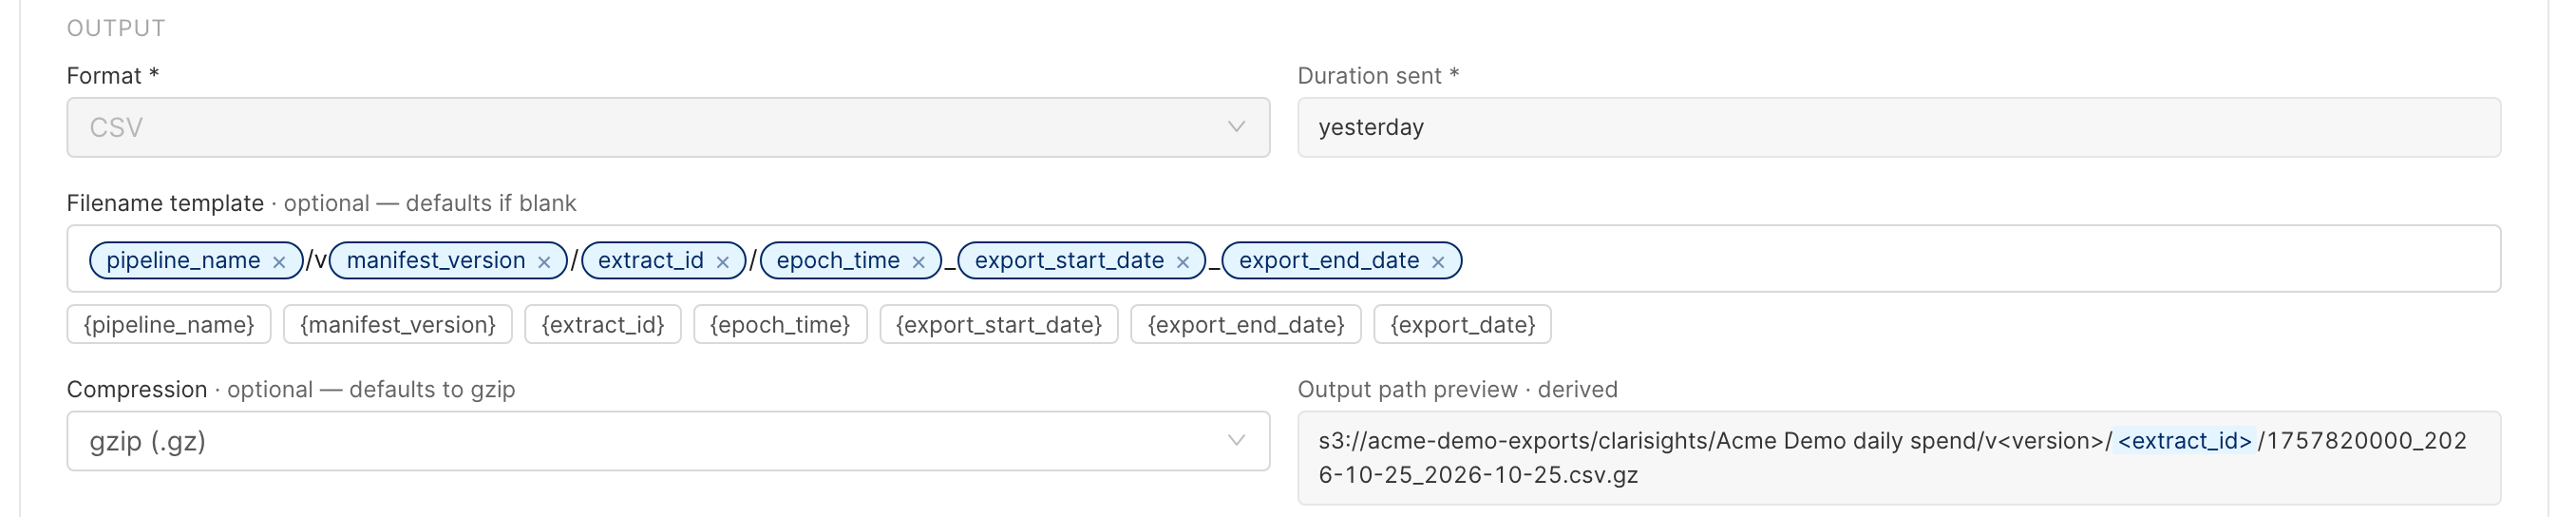
The template sets the folders and the file name of each file inside the destination. If you leave it blank, the default is used:
{pipeline_name}/v{manifest_version}/{extract_id}/{epoch_time}_{export_start_date}_{export_end_date}
The destination's path prefix goes in front, and .csv or .csv.gz is added at the end. Next to each file, a .meta.json file with the same name describes its columns. Output path preview shows an example path for the current settings.
Click a token to add it to the template:
Token | Replaced with |
| The pipeline's name. Renaming the pipeline sends new files to a new folder. |
| The version number. The default template puts a |
| The extract ID. Required. |
| The time the run started, as a Unix timestamp in seconds |
| The first and last date of the exported data (YYYY-MM-DD) |
| The date of the run in the schedule's timezone (YYYY-MM-DD) |
Rules:
If the live version, or a previous version still in its 30-day overlap, has more than one extract, the template must include
{extract_id}, so each extract gets its own file. With one extract, it's optional.It can't contain
.., so paths can't point outside the destination.A
/creates a folder. Text that isn't a token, including a mistyped token, stays in the path as it is.
Important: Keep
{manifest_version}in the template. For 30 days after each publish, the previous version is exported too. Without the version in the path, both versions' files share a folder (told apart only by{epoch_time}) or, without{epoch_time}either, overwrite each other. The editor warns you when the version is missing.
Schedules saved before these rules show Legacy filename template. They keep exporting as they are, but when you edit the template it must follow the rules. A draft with two or more extracts can't be published while an active schedule's template has no {extract_id}.
Schedule names
You don't name schedules: Clarisights names each one after its destination and cadence, for example "acme-exports-s3 - daily at 6:00 am". The name updates when you change either, and two schedules can have the same name.
Run now
Run now starts an export straight away, without waiting for the cadence. Use it to test a schedule, to resend a period, or to export history.
On the pipeline's Schedules tab, click Run now on the schedule.
Under Date range for this run, choose Schedule's range to use the schedule's own date range, or Pick dates to set a Start date and End date.
Click Run export.
Wait for the runs to appear, then follow them on the Runs tab.
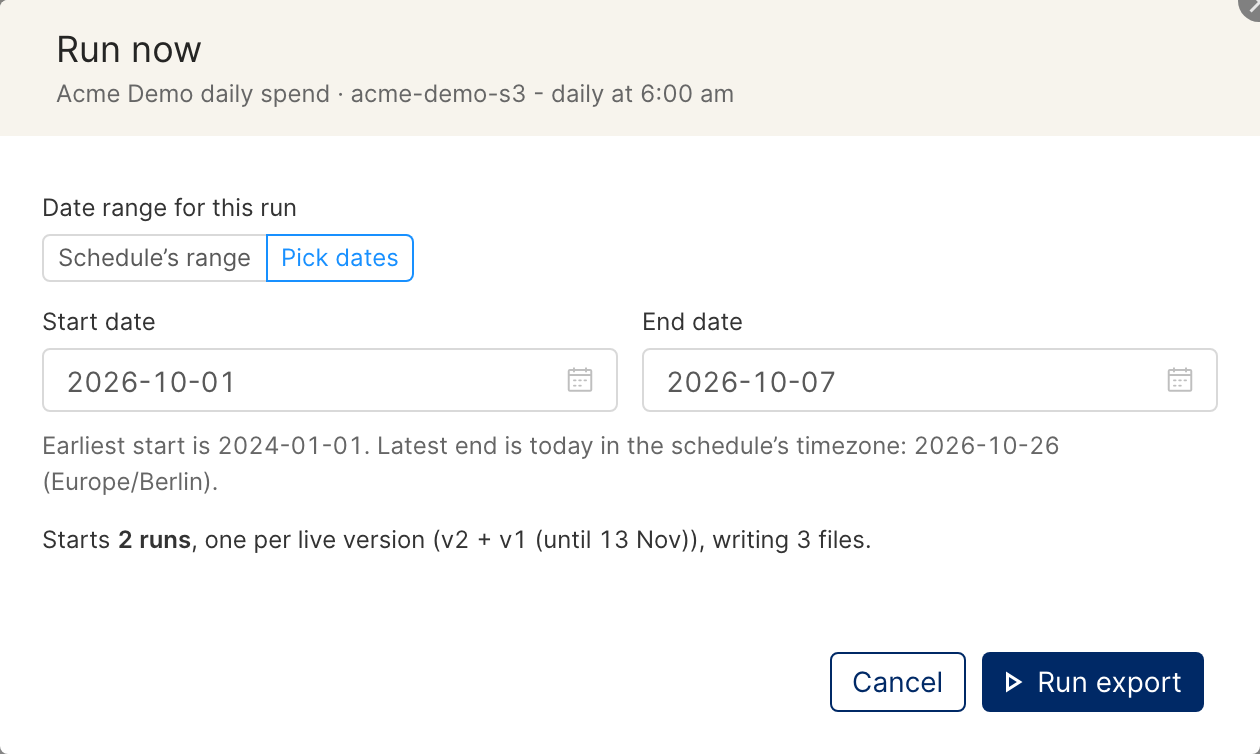
Dates: the earliest start is 1 January two years back (for example 1 January 2024 during 2026). The latest end is today in the schedule's timezone.
Files: each run writes one file per extract for the whole range. It isn't split by day: add the Date dimension to the extract to get daily rows.
Versions: it starts one run per exporting version, so during a 30-day overlap you get files for both versions.
Cadence: it doesn't change when the schedule runs next.
No duplicate check: every click starts new runs. If no run shows up within a minute, check the Runs tab again a few minutes later before clicking again, or you get duplicate files.
When it's unavailable: Run now needs a published version, an active schedule, an active pipeline and a destination that still exists. Hover over the button to see which one is missing.
To repeat a failed run, open it on the Runs tab and click Retry with the same dates. This opens Run now with the failed run's dates filled in.
Exporting historical data
To load past data into your warehouse, for example when you start using a pipeline, use Run now with your own dates:
Make sure the extracts include Date (or another time dimension), so the history comes in as daily rows rather than one total.
On the Schedules tab, click Run now on the schedule that delivers to the right destination.
Choose Pick dates. Set the Start date as far back as you need (at most 1 January two years back) and the End date to yesterday.
Click Run export, then check the files on the Runs tab.
A long range gives one large file per extract. To keep files smaller, run the history in several parts, for example one year or one quarter at a time. With the default template each run's file name has its own dates and timestamp, so the parts don't overwrite each other.
Pausing and resuming
A schedule: on the Schedules tab, click Pause on its row. It stops running until you click Resume. Other schedules keep running.
The whole pipeline: on the pipeline page, open the ⋯ menu and click Pause pipeline. No schedule runs and Run now is unavailable, but previews still work. Resume it with Resume pipeline in the same menu.
While the pipeline is paused, its active schedules still show Active, with a note that they won't run until the pipeline resumes.
If a paused schedule's destination was deleted, resuming it asks you to choose another destination first.
Editing and deleting schedules
Editing: click Edit on the schedule's row, change the settings, then click Save schedule. Changes apply from the next run.
Deleting a schedule: open the ⋯ menu on its row, click Delete, then Delete schedule. It stops sending files. Files already in your storage stay, and runs that have already started finish as normal.
Deleting the pipeline: on the pipeline page, open the ⋯ menu and click Delete pipeline. All its schedules stop and files already in your storage stay, but the pipeline's runs history is no longer visible. This can't be undone from the app.
Checking runs
The pipeline's Runs tab lists every run from the last 30 days, scheduled or started with Run now, with its status (Running, Succeeded or Failed), version, dates, files and rows. To see one schedule's runs, open the ⋯ menu on its row and click View runs. Click a run to see each file with its row count and size.
There are no email or Slack alerts for failed runs. Failures show on the Runs tab and at the top of the Export pipelines list. If a run fails, see Troubleshooting Export Failures.