Getting Started with Export Pipelines
Export Pipelines deliver your Clarisights data to your own cloud storage (Amazon S3, Google Cloud Storage or Azure Blob Storage) on a schedule. You choose what to export, where it goes and when, and you set it all up yourself in Clarisights.
Who can use Export Pipelines
Users with the Admin or Data Manager role can create and manage export pipelines and destinations.
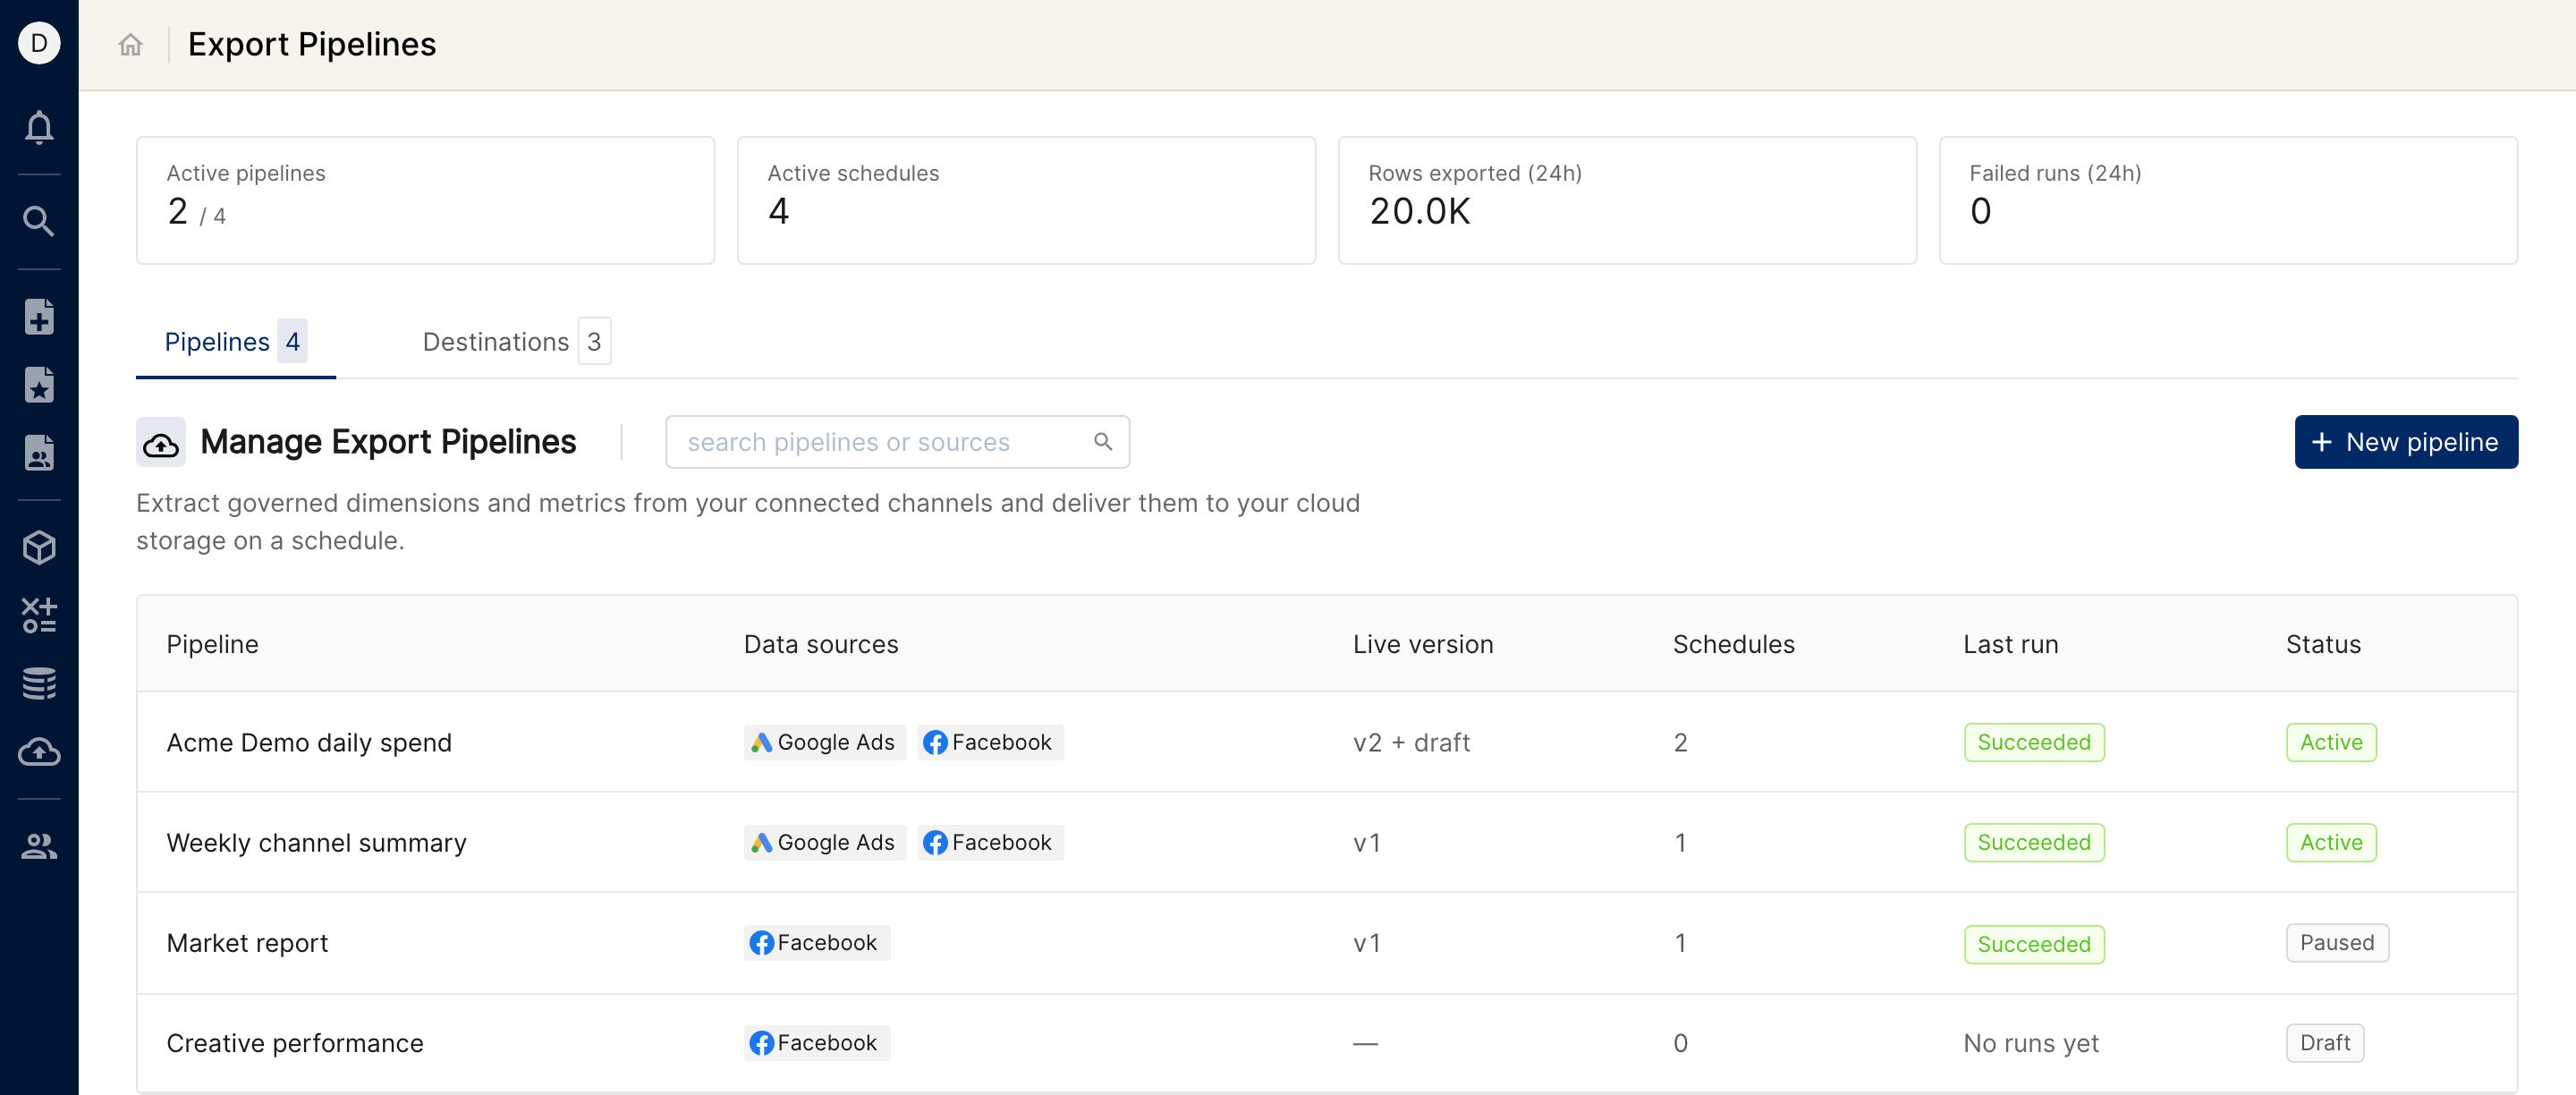
Open it from the Export pipelines icon (a cloud with an arrow) in the left sidebar, just below Integrations.
Users without one of these roles don't see the icon. If you need access, ask a workspace admin to give you the Admin or Data Manager role, then reload the page.
Key concepts
Concept | What it is |
Pipeline | The container for one export: a name, its data sources, its extracts, its schedules and its run history. |
Sources | The connected channels the pipeline reads from (for example Google Ads and Facebook). The dimensions and metrics you can export come from these sources. |
Extracts | What to export. Each extract is one output table with its own dimensions, metrics and filters, and becomes one file per run. See Extracts, Drafts & Versions in Export Pipelines. |
Draft and versions | You edit extracts in a shared draft. Publishing the draft makes it a numbered, read-only version (v1, v2 and so on) that starts exporting. To change a live pipeline, you start a new draft and publish it as the next version. |
Schedules | When to export and where to: a cadence, a timezone, the date range each run covers, the destination and the file name template. A pipeline can have several schedules. See Managing Export Schedules. |
Destinations | The bucket or container your files go to, with the access details Clarisights uses. Destinations belong to the workspace and can be reused by any pipeline. See Configuring Export Pipeline Destinations & Permissions. |
Runs | One export of one version for one schedule, with its status, dates, rows and files. The Runs tab of a pipeline shows the last 30 days. |
What's supported
Destinations: Amazon S3, Google Cloud Storage and Azure Blob Storage.
Format: CSV with a header row.
Compression: gzip (the default) or none.
Cadence: hourly, every few hours, daily, weekly, or a custom cron expression, at most once an hour, in the timezone of your choice.
Date range per run: presets such as Yesterday, Last 7 Days and Last 30 Days, or a custom range with relative or fixed start and end dates.
On-demand runs: Run now on any schedule, with the schedule's own date range or dates you pick (for example to backfill past dates).
Row limit: none. Each extract is delivered as a single file, however many rows it has.
Creating your first pipeline
Before you start, make sure you have a bucket or container that Clarisights can read from and write to. You can add the destination while you create the schedule, but the access must be granted on your side first. See Configuring Export Pipeline Destinations & Permissions.
The New pipeline wizard has four steps: Sources, Extracts, Schedule and Review & publish. Your work is saved as a draft from the end of the first step, and nothing exports until you publish.
Step 1: Sources
Click the Export pipelines icon in the left sidebar, then click New pipeline.
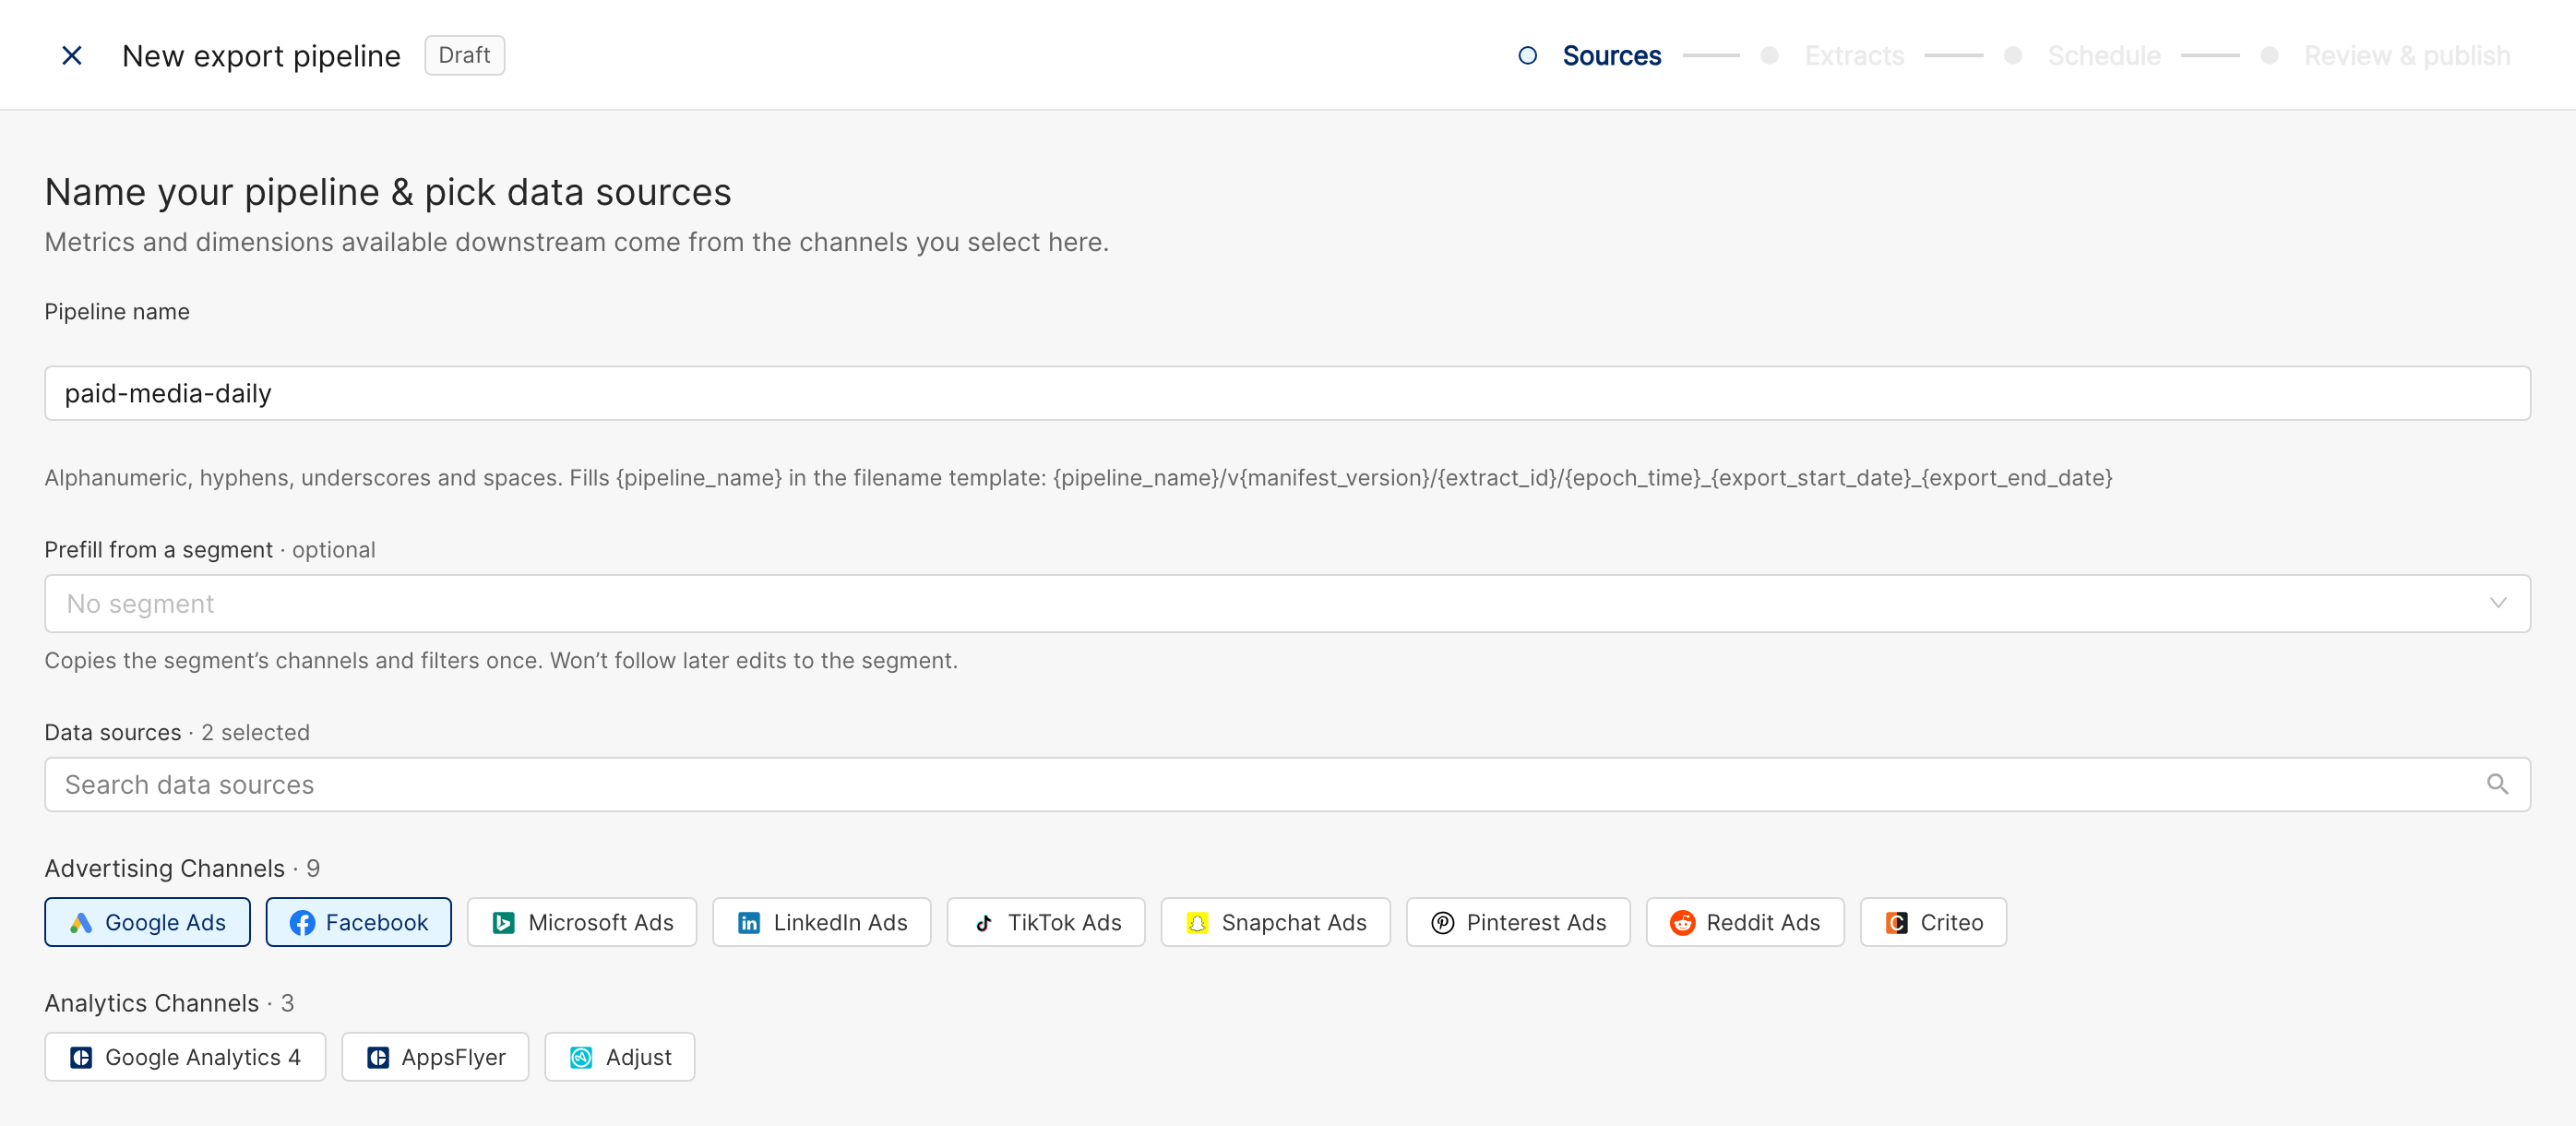
Enter a Pipeline name, for example
paid-media-daily. Use letters, numbers, hyphens, underscores and spaces. The name must be unique in your workspace, and with the default file layout it becomes the top folder of your files, so pick one your downstream jobs can rely on.Optional: under Prefill from a segment, pick a segment to copy its channels and filters. They are copied once: later edits to the segment don't change the pipeline.
Under Data sources, select the channels to export from.
Click Continue. The pipeline is now saved as a draft.
Step 2: Extracts
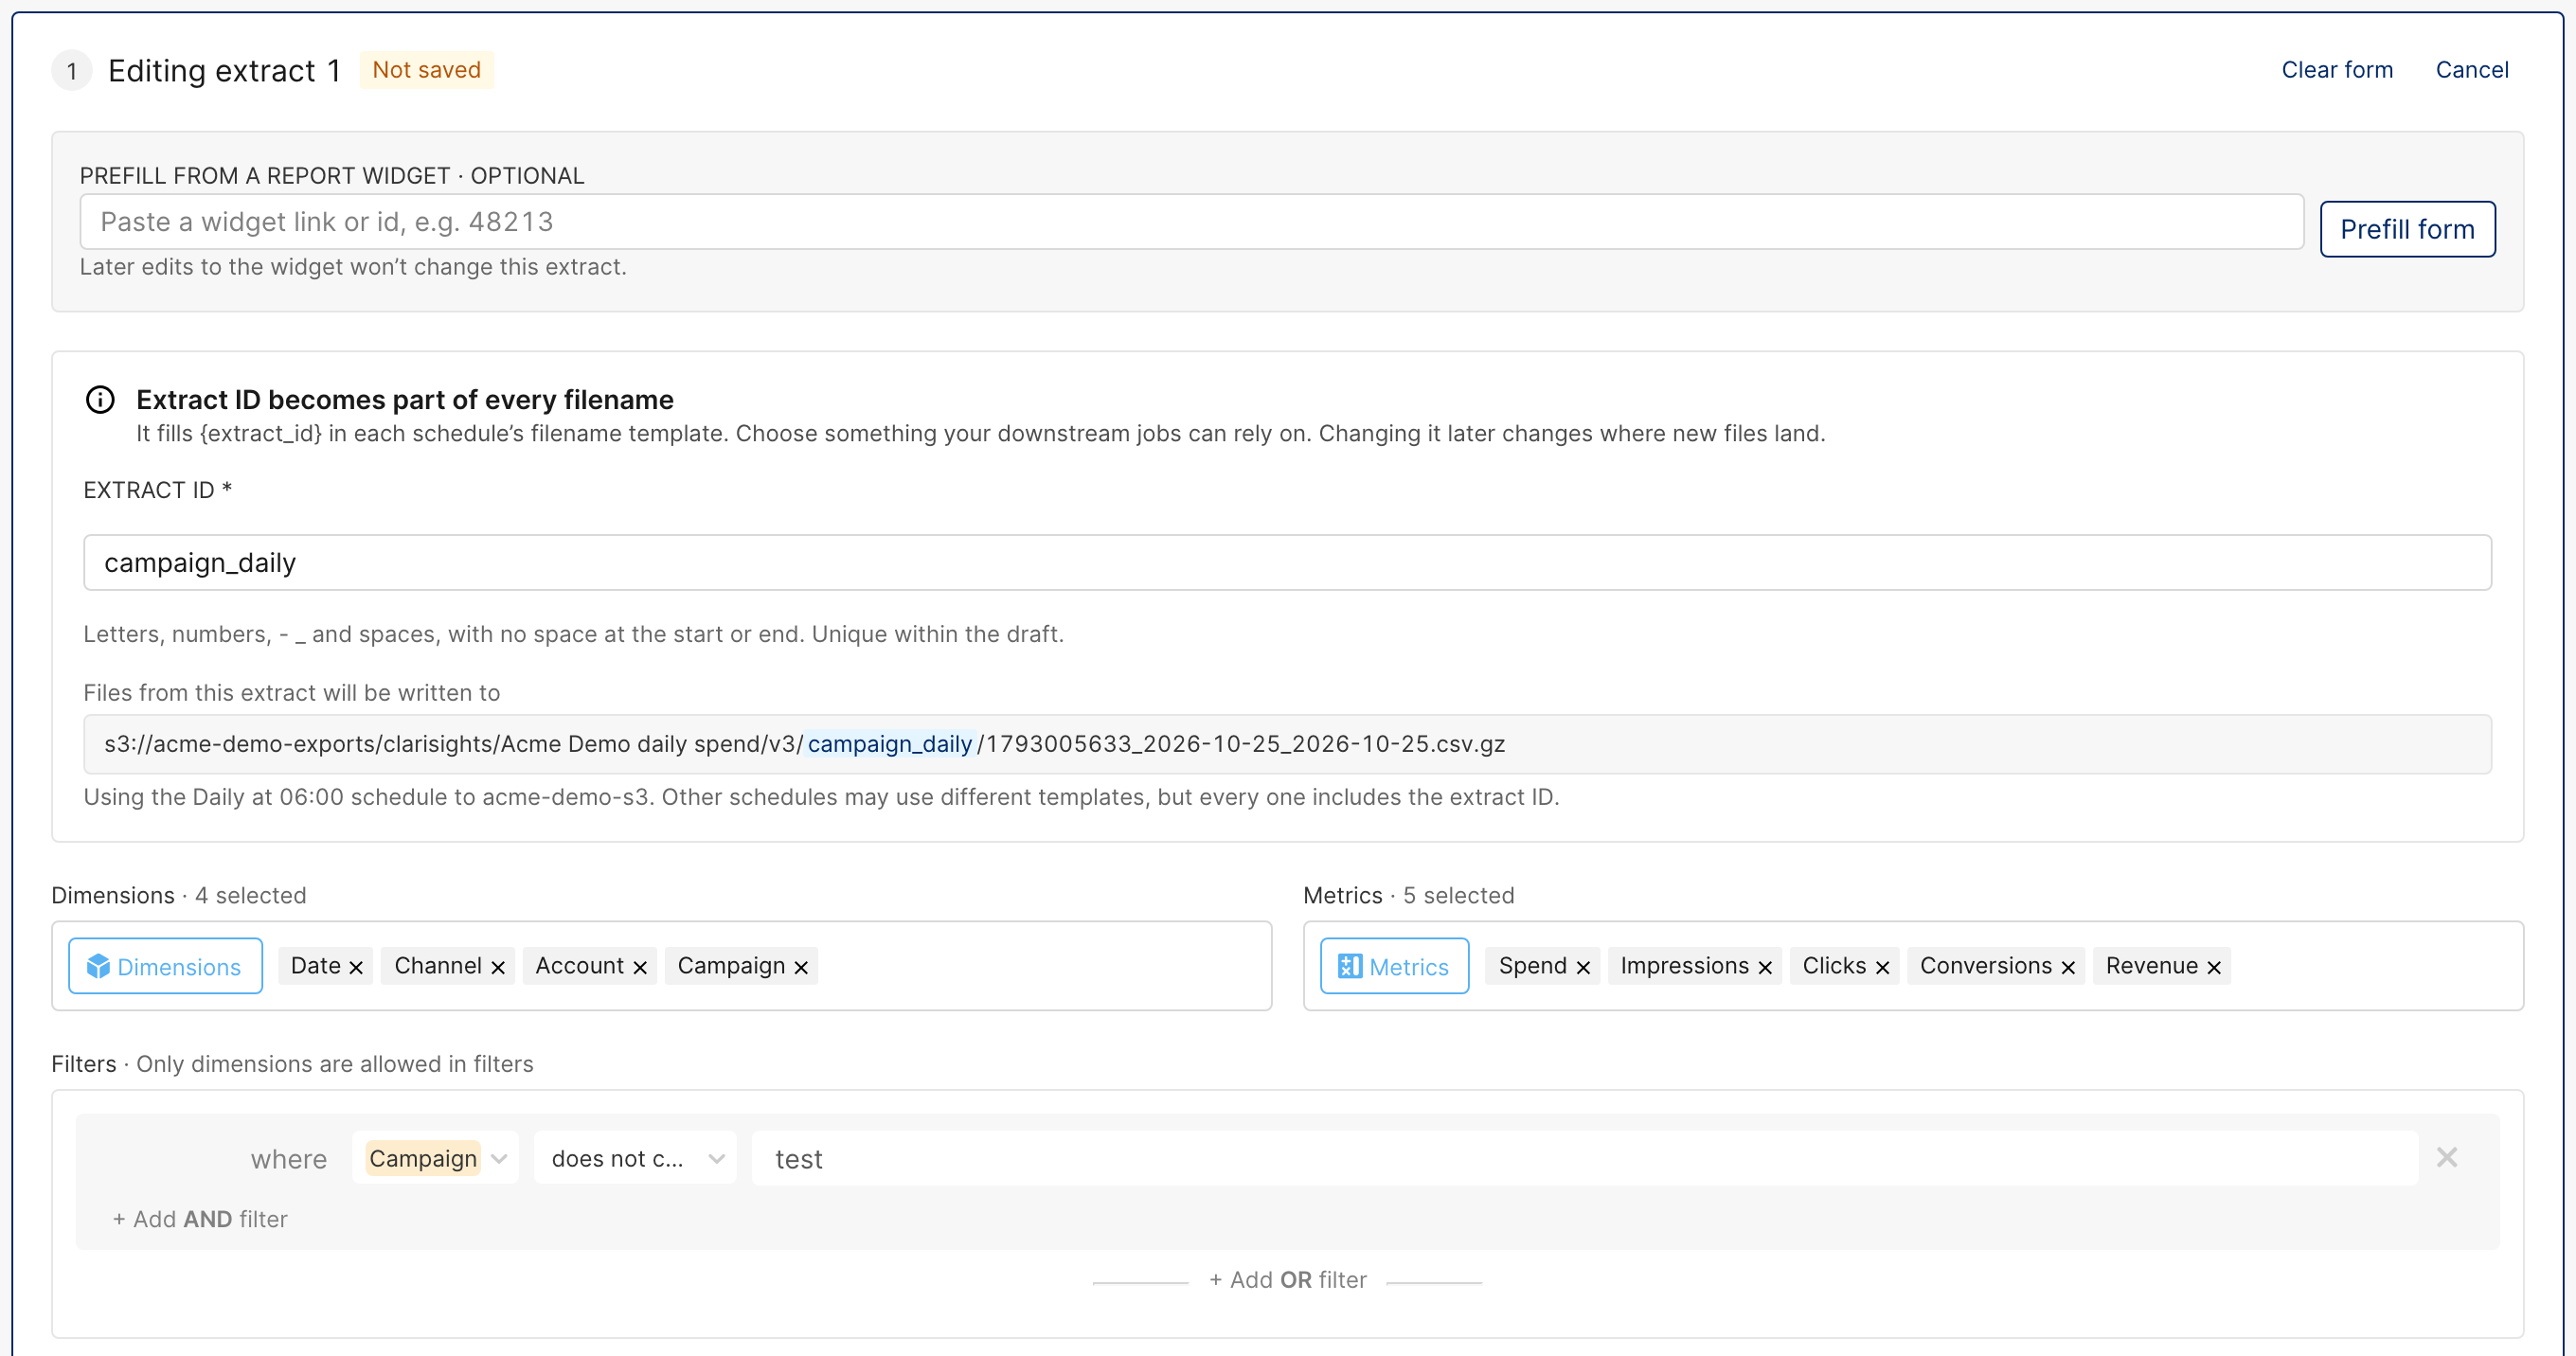
Optional: under Prefill from a report widget, paste a widget's link or ID and click Prefill form. Clarisights copies the widget's dimensions, metrics and filters, and lists any fields that aren't available from the pipeline's sources.
Enter an Extract ID, for example
blended_daily. It becomes part of every file name of this extract, so changing it later changes where new files land.Pick the Dimensions and Metrics to export. Each row of the file is one combination of the dimensions over the whole date range of the run, so add Date if you want one row per day.
Optional: add Filters. Only dimensions can be used in filters, and time dimensions such as Date or Month can be exported but not filtered.
Optional: click Run preview to see the rows the extract would produce. The preview writes nothing.
Click Save to draft. To export another table, click Create new extract and repeat.
Click Continue.
Step 3: Schedule
This step is optional. Click Skip for now to add schedules later from the pipeline's Schedules tab.
Under Destination, pick where the files go, or choose + Create new destination… to add one.
Under Cadence, choose how often to export. New schedules start on Hourly, so for most uses choose Daily and set a time.
Under Timezone, keep the company default or pick another timezone. The cadence and the date range follow this timezone.
Under Preset, choose the date range each run covers. The default is Last 7 Days, which means the 7 full days before the day of the run.
Leave the file name template and compression blank to use the defaults, or change them.
Click Save schedule. The schedule waits and starts after you publish.
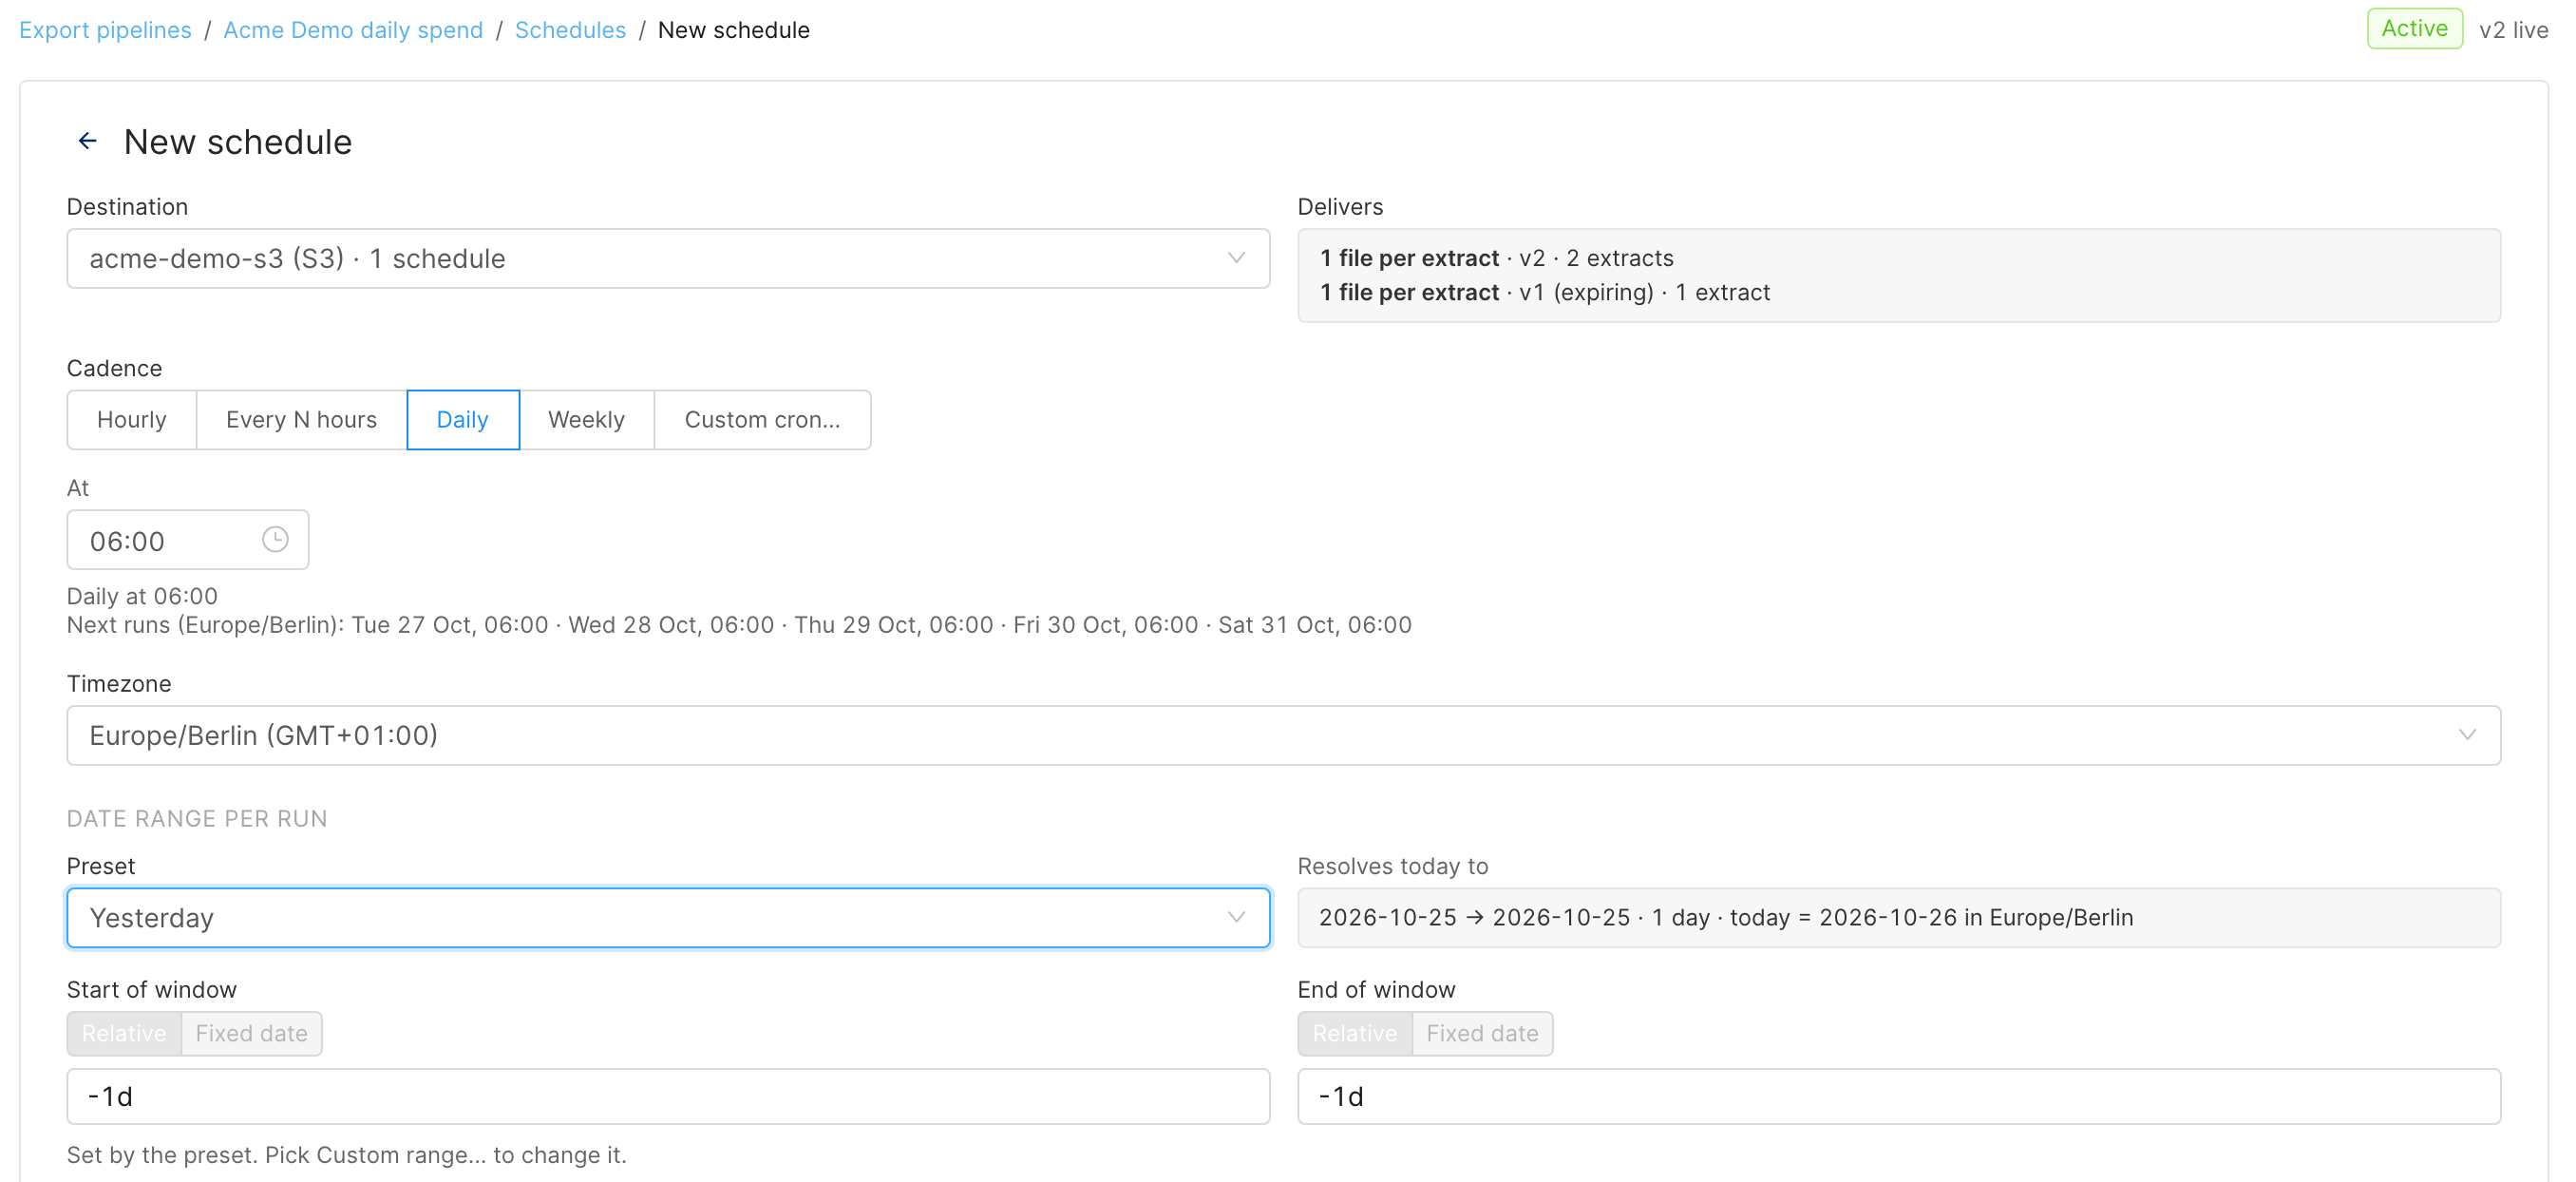
Tip: every run exports the whole date range again. An hourly schedule with Last 7 Days sends 24 copies of the last 7 days every day, so pick Daily unless you need fresher files. For help choosing a time and range, see Export Scheduling & Timing Guide.
Step 4: Review & publish
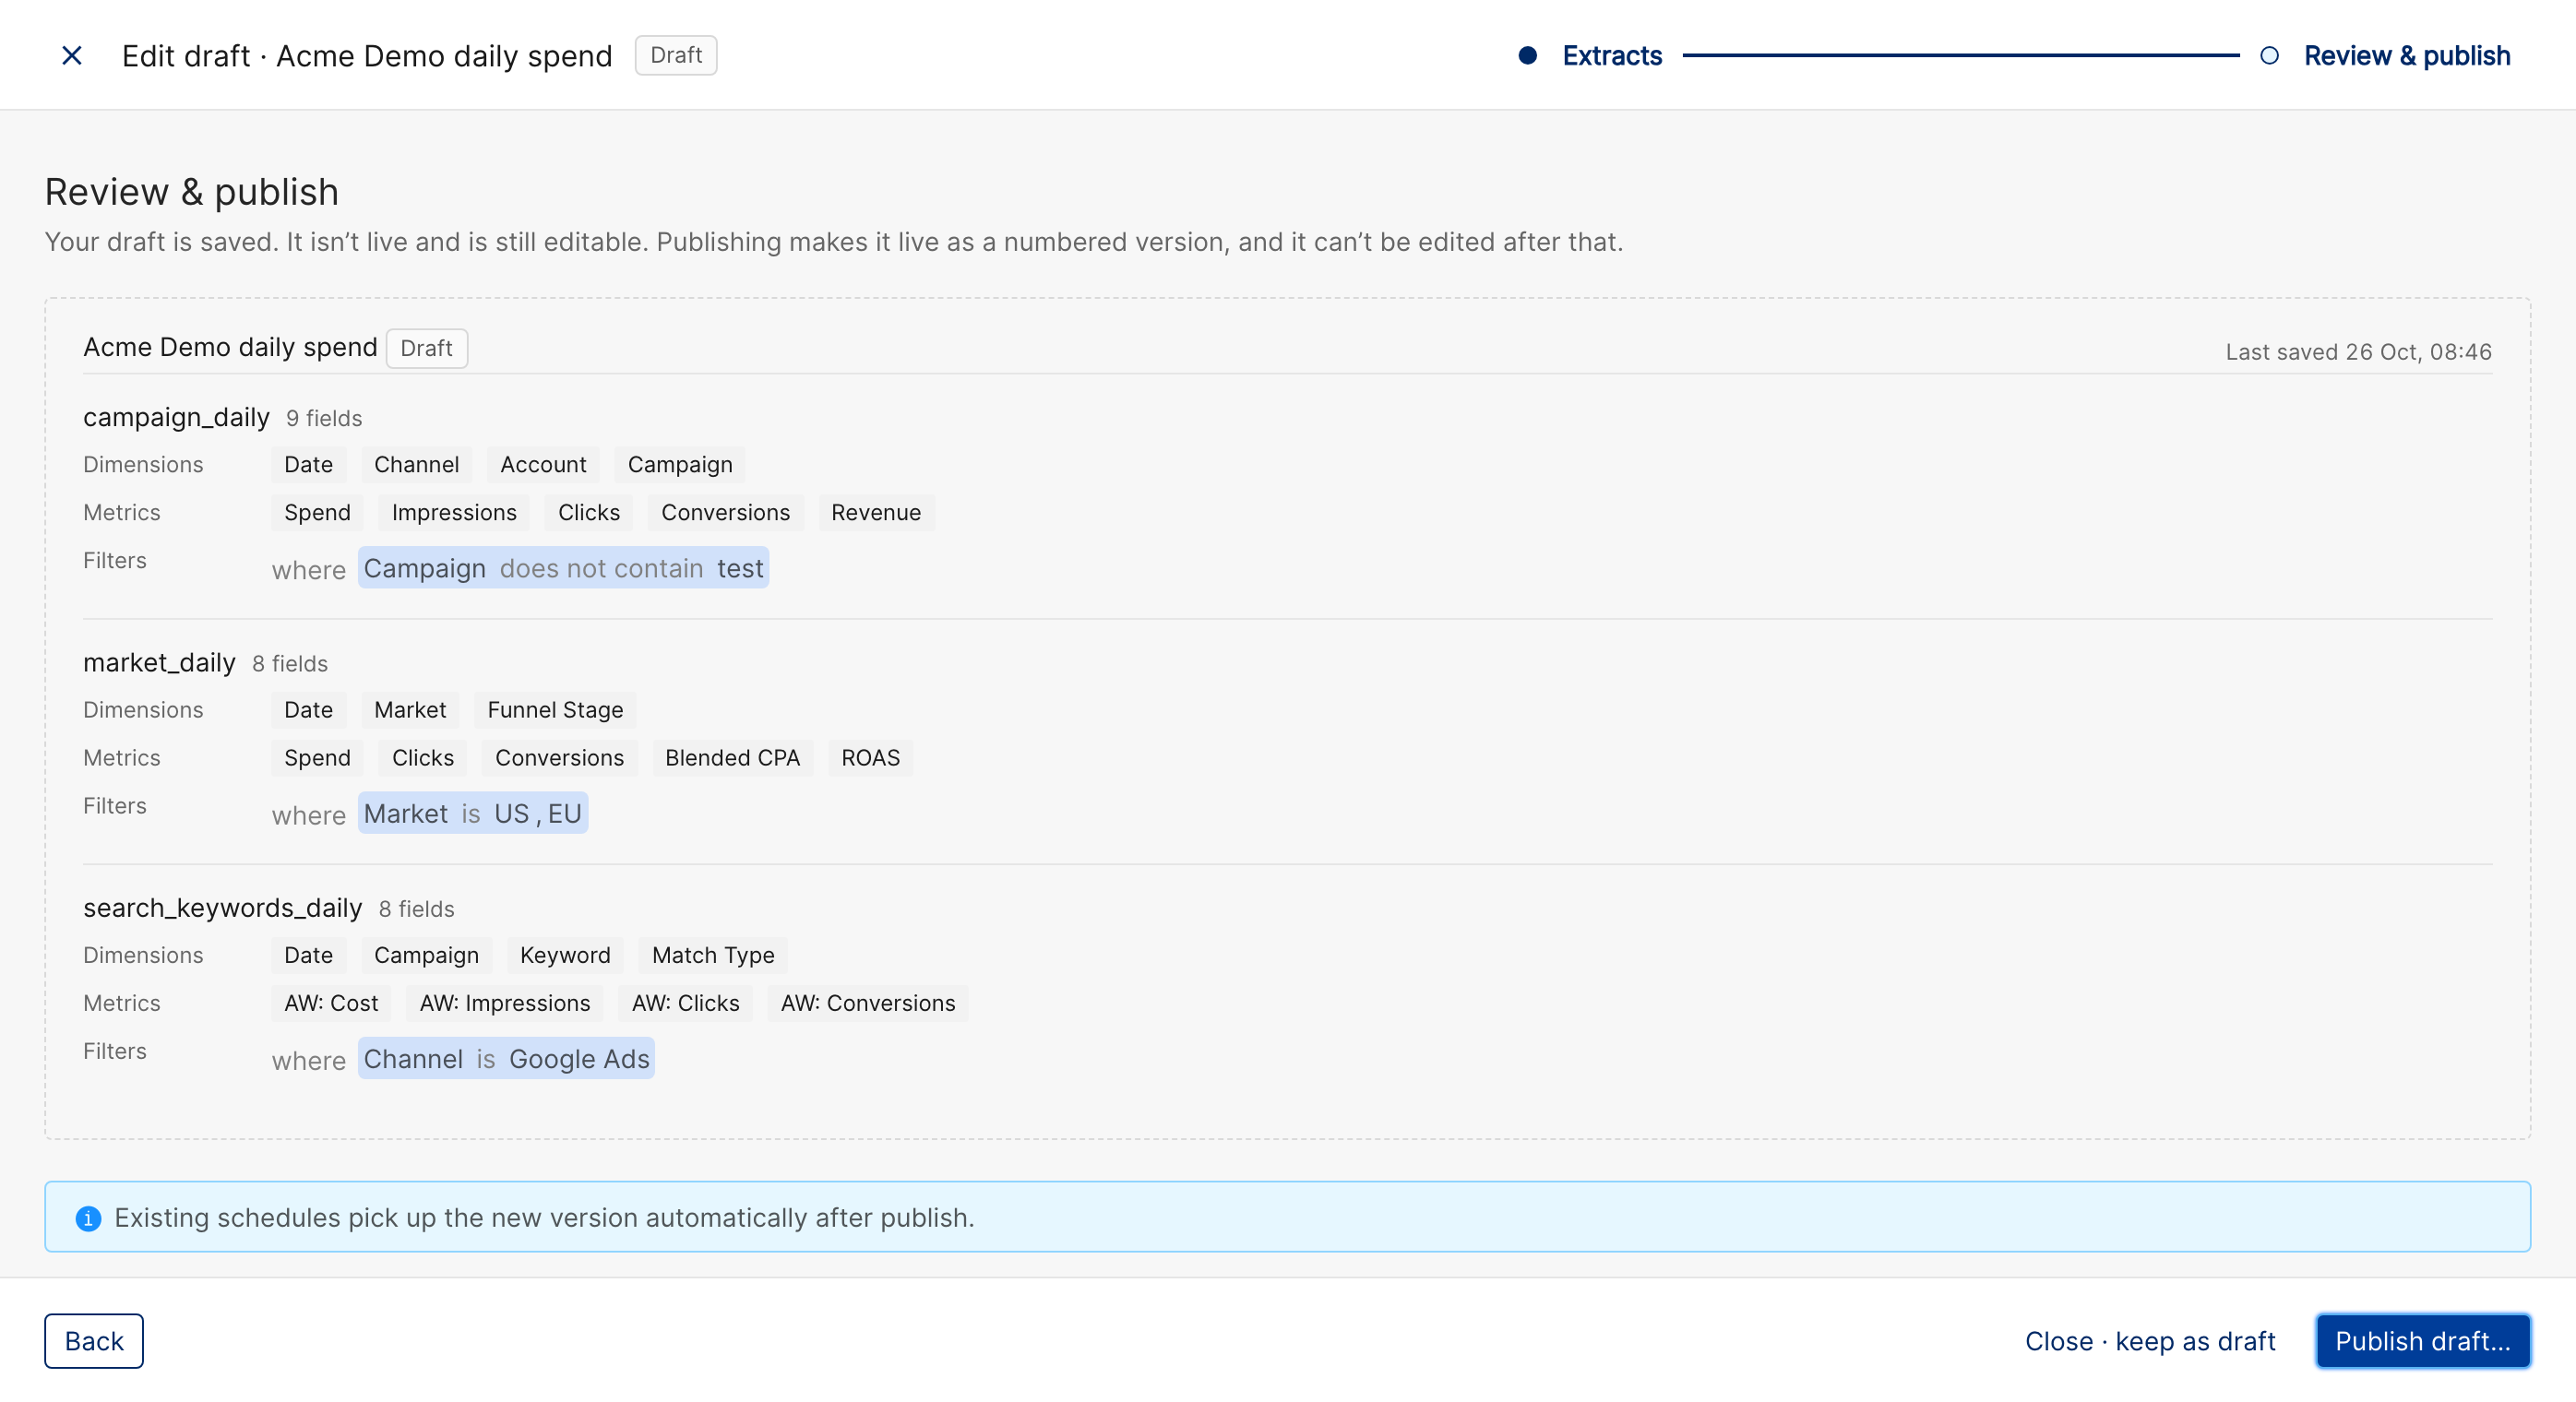
Check the extracts and the schedule. To finish later, click Close · keep as draft.
Click Publish draft….
Read the summary of what will happen, then click Publish as v1.
What happens when you publish
The draft becomes version v1, which can't be edited. To change the pipeline later, click New draft (or Open draft) on the pipeline page and publish the draft as the next version.
If the pipeline has a schedule with a destination, the first export usually starts right away. Clarisights shows it starting, and you can follow it on the Runs tab. If it doesn't start, it runs at the next scheduled time instead.
If there is no schedule yet, nothing is delivered until you add one with New schedule. Adding a schedule to a published pipeline usually starts an export right away too.
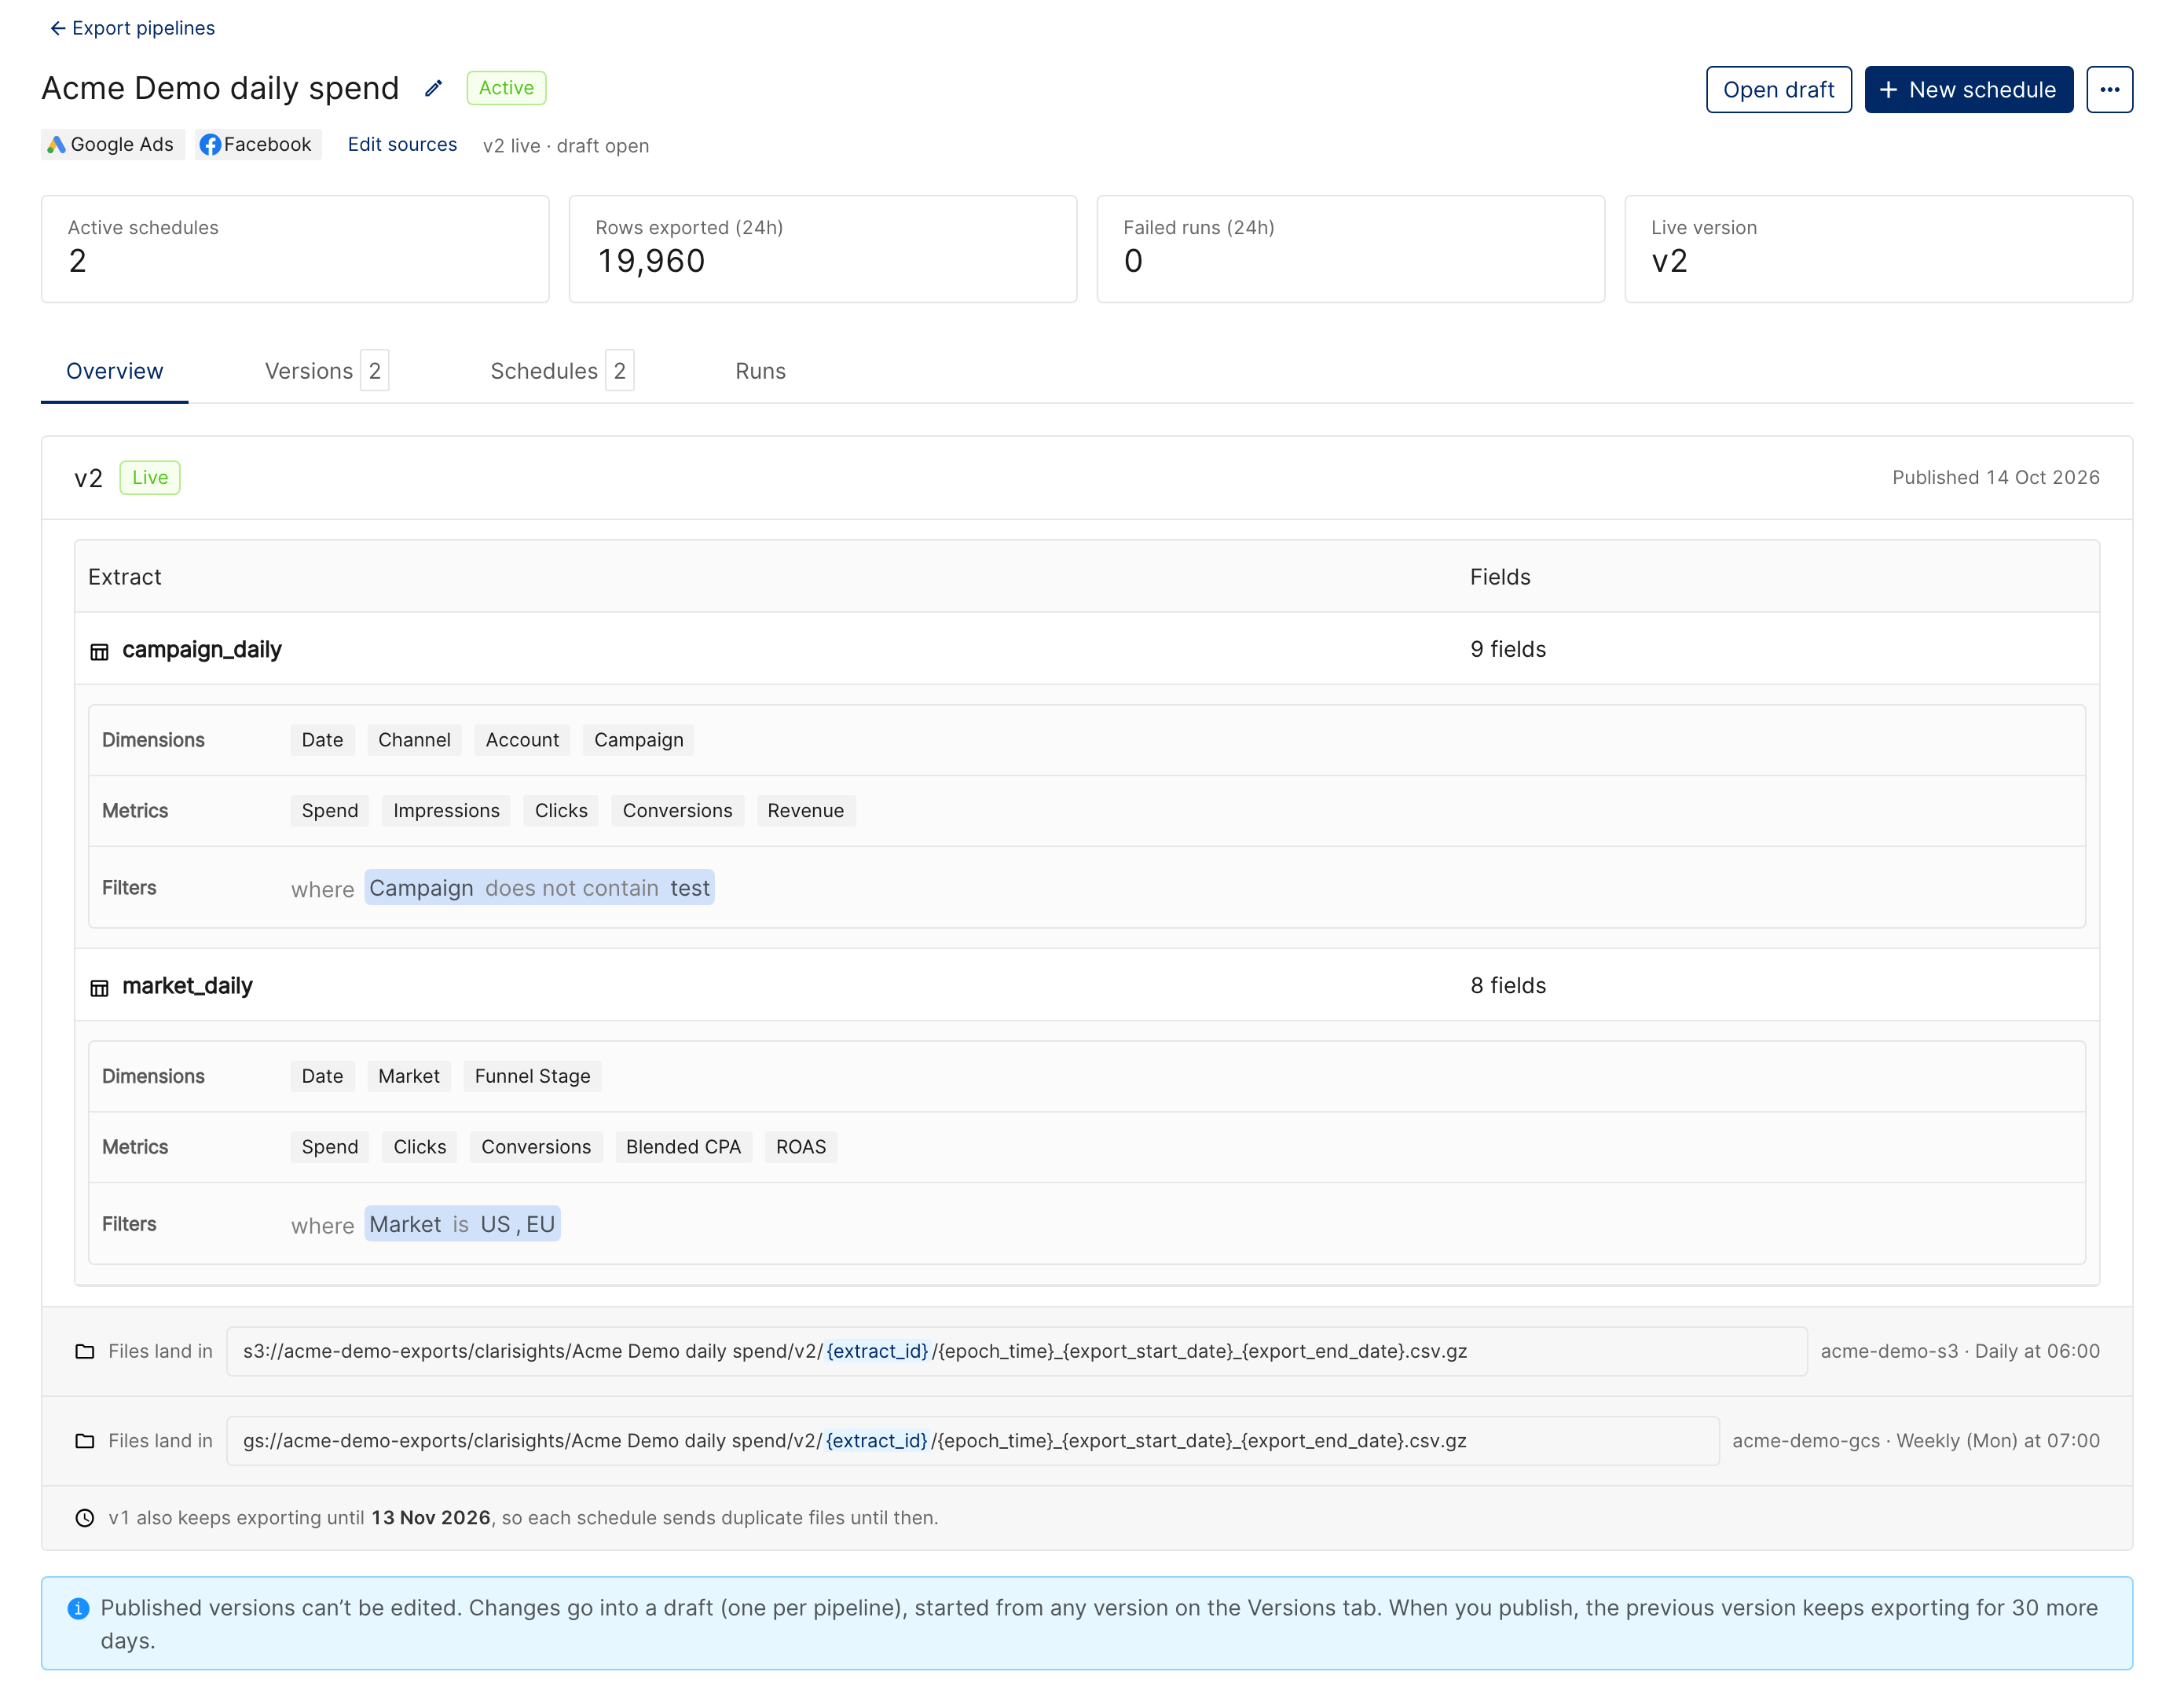
When you later publish a new version, the previous version keeps exporting for 30 days, so each run sends files for both. With the default layout each version writes to its own
v1,v2folder.There are no email or Slack alerts. Failed runs show on the Runs tab and in the "need attention" banner at the top of the Export pipelines page.
What gets exported
Each run writes two files per extract, for every version that is still exporting:
A CSV data file, gzip-compressed unless you chose no compression. Dimension columns are named as in Clarisights, metric columns use the metric's key, and an extra
_extracted_atcolumn holds the time of the export.A metadata file (
.meta.json) next to it, with the date range, the row count and a column mapping that gives each metric's name as shown in Clarisights.
With the default file name template, files are organized in your bucket as:
{path_prefix}/{pipeline_name}/v{manifest_version}/{extract_id}/{epoch_time}_{export_start_date}_{export_end_date}.csv.gz
The path prefix comes from the destination, and you can change the rest with the schedule's file name template. See File structure in your bucket and Managing Export Schedules.
Pipeline status and lifecycle
The pipeline list and the pipeline page show a status for each pipeline:
Active: published and scheduled. Its active schedules run on their cadence.
Paused: no schedules run and Run now is unavailable. Previews still work.
Draft: never published, or published but without a schedule yet.
To manage a pipeline, open it and use the ⋯ menu next to New schedule:
Pause pipeline stops all its schedules. Resume pipeline starts them again. To pause a single schedule instead, click Pause on its row in the Schedules tab.
Delete pipeline stops all its schedules and discards an open draft. Files already in your bucket stay where they are, but the pipeline's run history is no longer visible. You can't undo this from the app.
To rename a pipeline, click the pencil next to its name. With the default template, new files then go to a folder with the new name, so coordinate the change with anyone reading the old folder.
How is this different from Data Exporters and Widget Exports
Feature | Export Pipelines | Data Exporters (legacy) | Widget Exports (legacy) |
Set up by | You, in Clarisights (Admin or Data Manager) | The Clarisights team | The Clarisights team |
Choose metrics and dimensions | Yes | Fixed per channel | Linked to widget config |
Several channels in one file | Yes | No (one set of files per channel) | Linked to widget config |
Filters | Yes (dimension filters) | No | Linked to widget config |
Schedule | Hourly, every few hours, daily, weekly or custom (at most once an hour) | Daily, plus an optional run for the last 3 days | A chosen hour, every 1 to 24 hours |
Row limit | No limit (one file per extract) | No limit (may be split into parts) | 100,000 rows |
Versions | Yes (the previous version keeps exporting for 30 days) | No | No |
Test the connection to your bucket | Yes | No | No |
Note: Data Exporters and Widget Exports are being retired, and new Data Exporters can no longer be set up. Existing legacy exports keep running for now. Once your export pipeline delivers what you need, ask us to switch the legacy export off: click ? at the bottom right of Clarisights and choose Send us a message. See Migrating from Legacy Exports to Export Pipelines.
If a run fails, see Troubleshooting Export Failures.